LLM Integration: Moving from Prototype to Production Without Burning Your Budget
A production LLM feature needs evaluation, cost controls, retrieval and permission decisions, fallback behavior, and observability beyond the initial prototype. This guide explains the core architecture choices.
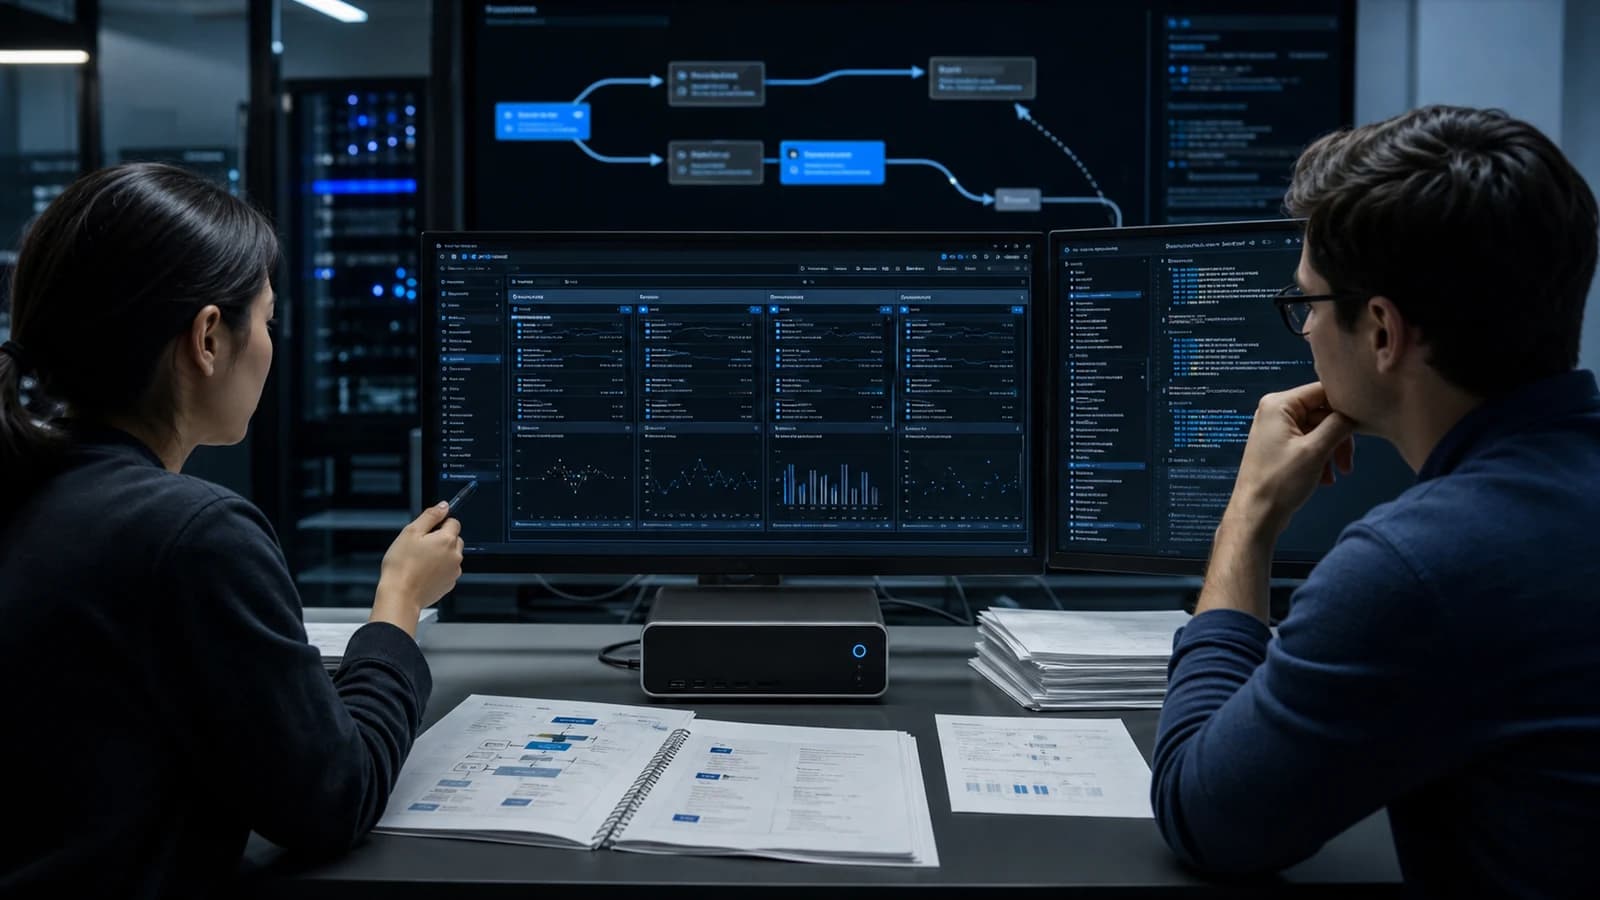 Production LLM loop
Decision brief
The short answer
A production LLM feature needs an evaluation set, validated inputs and outputs, observable quality and cost, explicit failure behavior, and a fallback appropriate to the user job. Prompt quality matters, but the application boundary around the model determines whether the feature can be operated safely.
Evaluate representative and adversarial tasks before changing prompts or models.
Validate structured outputs and tool arguments before trusted systems use them.
Measure quality, latency, refusal, cost, and recovery on the same release candidate.
At a glance
What to carry into the decision
- Define an evaluation set from real tasks before optimizing prompts or swapping models.
- Validate structured outputs and tool arguments at a trusted application boundary.
- Measure quality, latency, cost, refusal, and recovery behavior together.
A convincing AI prototype can be quick to assemble. Making it production-ready requires architecture, evaluations, failure handling, and operating controls. The gap between a working demo and a system that handles variable traffic while controlling unsupported outputs, timeouts, and API spend is where many projects stall. Here is how to cross that gap.
Why Prototypes Fail in Production
Your prototype works because you are testing it with 5 handpicked queries and a single user. Production is different. Production means:
- Concurrent users hitting your API with overlapping requests
- Edge cases your test dataset never covered
- Context windows that overflow when users paste in 50-page documents
- API rate limits that throttle your throughput during peak hours
- Model degradation when OpenAI or Anthropic quietly updates their weights
Each of these can expose assumptions that were invisible in a controlled prototype.
The Production LLM Architecture
A production LLM system is not "call the OpenAI API and return the response." It is an orchestration layer that manages retrieval, context construction, model routing, caching, fallbacks, and observability.
Retrieval-Augmented Generation (RAG)
RAG is useful when an application must answer from company-specific or frequently changing knowledge. It is not automatically the right architecture for every feature; the retrieval requirement and evaluation criteria should be explicit.
A common architecture chunks documents into semantically meaningful segments, embeds them, stores the vectors in a suitable database, and retrieves ranked context for each query. Chunking, embedding, ranking, and citation behavior should be tuned against representative questions instead of copied from a default recipe.
Context Window Management
Every model has a finite context window, and provider limits change over time. Even a large context can be exhausted by long documents, retrieved evidence, tool output, and conversation history, so read the current provider documentation during implementation.
You need a context budget strategy: allocate fixed token budgets for system instructions, retrieved documents, conversation history, and the user's current query. When the budget overflows, apply a prioritized truncation strategy - older conversation turns get dropped first, retrieved documents get re-ranked and trimmed, and system instructions never get cut.
Model Routing and Fallbacks
Not every query needs the same model class. A routing step can send straightforward lookups to a lower-latency option while reserving higher-capability models for tasks that pass a complexity threshold. Select the current models from your own quality, privacy, latency, and cost evaluation.
Define intentional failure behavior. For a retryable provider error, use bounded exponential backoff and respect provider guidance. Use an alternative model or provider only when its output has been evaluated for the same task. Otherwise fail clearly, preserve state, and let the user retry safely.
Cost Optimization Strategies
LLM API costs can spiral out of control without active management. Here are the levers you have:
Semantic Caching
If measured traffic contains repeatable, safe-to-reuse results, caching can reduce duplicate provider calls. Define cache keys, tenant boundaries, freshness, invalidation, and similarity thresholds from evaluation data; semantic caching is unsafe when small input differences can materially change the correct answer.
Prompt Compression
Many prompts contain redundant context. Compression or manual prompt optimization can reduce token use, but any change must be checked for lost instructions, missing evidence, and quality regressions. Token reduction does not translate directly to total cost when caching, output tokens, retrieval, and other services are involved.
Batch Processing
For non-real-time workloads such as document processing or data enrichment, evaluate provider batch interfaces and queued processing. Discounts and limits change, so treat the current provider price sheet as the source of truth rather than embedding a permanent percentage in the architecture.
Observability Is Non-Negotiable
If you cannot trace every LLM call in your system - the prompt that went in, the response that came out, the latency, the token count, and the cost - you are flying blind.
Use tools like LangSmith, Helicone, or Braintrust to log every interaction. Set up alerts for latency spikes, cost anomalies, and hallucination signals (responses that contradict your retrieved documents). Review your trace logs weekly to identify prompts that consistently underperform.
Without observability, you will not know your system is failing until your customers tell you. And by then, you have already lost their trust.
The Production Readiness Checklist
Before shipping an LLM feature to production, verify:
- Rate limiting: Your system gracefully handles API throttling
- Evaluated fallback paths: An approved alternative is used only for compatible tasks and failures
- Context management: Overflow is handled without data loss
- Cost controls: Per-user and per-day spending caps are enforced
- Observability: Every call is traced, logged, and alertable
- Evaluation: A versioned set of representative queries runs before deployment, with size based on the important request classes and failure modes
Evidence and scope
What this guide is based on
The architecture patterns must be adapted to the model, data sensitivity, latency target, and cost envelope. Provider behavior and limits should be verified before launch.
Intended for: Product teams moving an LLM proof of concept into a customer-facing workflow.
Frequently Asked Questions
What is RAG and why is it necessary for production LLM apps?+
How do you prevent LLM hallucination in production?+
How much do LLM APIs cost for a production application?+
Related Articles
Written by
Zamad Shakeel
Founder & CEO, ZamDev AI · Full-Stack Engineer & AI Systems Builder
Zamad designs and ships AI products, agentic workflows, enterprise automations, and the production controls that make those systems dependable after launch.
linkedin.com/in/zamad-gopang →Turn the decision into a working system.
ZamDev AI helps teams design and deliver AI products, connected automations, knowledge systems, and production improvements with a clear scope and measurable acceptance criteria.
Or WhatsApp us directly: +92 328 635 6880